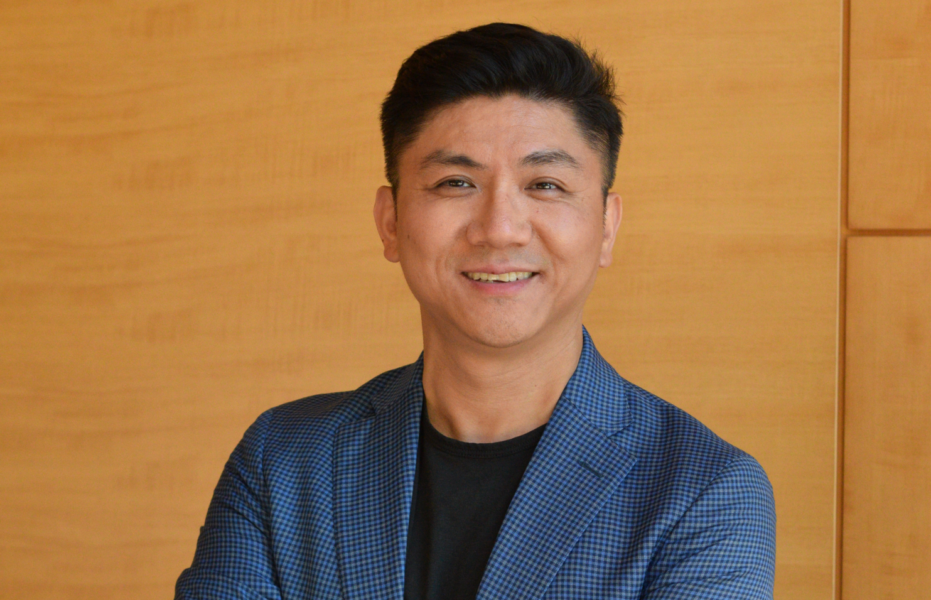
Charles Xie is the founder and CEO of Zilliz, specializing in constructing next-generation databases and search applied sciences for AI and LLMs purposes. At Zilliz, he additionally invented Milvus, the world’s hottest open-source vector database for production-ready AI. He’s at present a board member of LF AI & Knowledge Basis and served because the board’s chairperson in 2020 and 2021. Charles beforehand labored at Oracle as a founding engineer of the Oracle 12c cloud database venture. Charles holds a grasp’s diploma in laptop science from the College of Wisconsin-Madison.
Zilliz is the staff behind LF AI Milvus®, a broadly used open-source vector database. The corporate focuses on simplifying knowledge infrastructure administration, aiming to make AI extra accessible to companies, organizations, and people alike.
Are you able to share the story behind founding Zilliz and what impressed you to develop Milvus and concentrate on vector databases?
My journey within the database area spans over 15 years, together with six years as a software program engineer at Oracle, the place I used to be a founding member of the Oracle 12c Multitenant Database staff. Throughout this time, I seen a key limitation: whereas structured knowledge was well-managed, unstructured knowledge—representing 90% of all knowledge—remained largely untapped, with just one% analyzed meaningfully.
In 2017, the rising capacity of AI to course of unstructured knowledge marked a turning level. Advances in NLP confirmed how unstructured knowledge may very well be remodeled into vector embeddings, unlocking its semantic which means. This impressed me to discovered Zilliz, with a imaginative and prescient to handle “zillions of information.” Vector embeddings turned the cornerstone for bridging the hole between unstructured knowledge and actionable insights. We developed Milvus as a purpose-built vector database to convey this imaginative and prescient to life.
Over the previous two years, the trade has validated this strategy, recognizing vector databases as foundational for managing unstructured knowledge. For us, it’s about greater than know-how—it is about empowering humanity to harness the potential of unstructured knowledge within the AI period.
How has the journey of Zilliz developed since its inception six years in the past, and what key challenges did you face whereas pioneering the vector database house?
The journey has been transformative. Once we began Zilliz seven years in the past, the actual problem wasn’t fundraising or hiring—it was constructing a product in fully uncharted territory. With no present roadmaps, greatest practices, or established consumer expectations, we needed to chart our personal course.
Our breakthrough got here with the open-sourcing of Milvus. By reducing boundaries to adoption and fostering group engagement, we gained invaluable consumer suggestions to iterate and enhance the product. When Milvus launched in 2019, we had round 30 customers by year-end. This grew to over 200 by 2020 and almost 1,000 quickly after.
As we speak, vector databases have shifted from a novel idea to important infrastructure within the AI period, validating the imaginative and prescient we began with.
As a vector database firm, what distinctive technical capabilities does Zilliz supply to assist multimodal vector search in trendy AI purposes?
Zilliz has developed superior technical capabilities to assist multimodal vector search:
- Hybrid Search: We allow simultaneous searches throughout totally different modalities, resembling combining a picture’s visible options with its textual content description.
- Optimized Algorithms: Proprietary quantization methods stability recall accuracy and reminiscence effectivity for cross-modal searches.
- Actual-Time and Offline Processing: Our dual-track system helps low-latency real-time writes and high-throughput offline imports, making certain knowledge freshness.
- Value Effectivity: Our Prolonged Capability cases leverage clever Tiered Storage to cut back storage prices considerably whereas sustaining excessive efficiency.
- Embedded AI Fashions: By integrating multimodal embedding and rating fashions, we’ve lowered the barrier to implementing advanced search purposes.
These capabilities permit builders to effectively deal with various knowledge sorts, making trendy AI purposes extra strong and versatile.
How do you see Multimodal RAG advancing AI’s capacity to deal with advanced real-world knowledge like photos, audio, and movies alongside textual content?
Multimodal RAG (Retrieval-Augmented Technology) represents a pivotal evolution in AI. Whereas text-based RAG has been outstanding, most enterprise knowledge spans photos, movies, and audio. The flexibility to combine these various codecs into AI workflows is vital.
This shift is well timed, because the AI group debates the bounds of accessible web textual content knowledge for coaching. Whereas textual content knowledge is finite, multimodal knowledge stays vastly underutilized—starting from company movies to Hollywood movies and audio recordings.
Multimodal RAG unlocks this untapped reservoir, enabling AI techniques to course of and leverage these wealthy knowledge sorts. It’s not nearly addressing knowledge shortage; it’s about increasing the boundaries of AI’s capabilities to higher perceive and work together with the actual world.
How does Zilliz differentiate itself from rivals within the quickly rising vector database market?
Zilliz stands out by way of a number of distinctive points:
- Twin Identification: We’re each an AI firm and a database firm, pushing the boundaries of information administration and AI integration.
- Cloud-Native Design: Milvus 2.0 was the primary distributed vector database to undertake a disaggregated storage and compute structure, enabling scalability and cost-efficiency for over 100 billion vectors.
- Proprietary Enhancements: Our Cardinal engine achieves 3x the efficiency of open-source Milvus and 10x over rivals. We additionally supply disk-based indexing and clever Tier Storage for cost-effective scaling.
- Steady Innovation: From hybrid search capabilities to migration instruments like VTS, we’re continuously advancing vector database know-how.
Our dedication to open supply ensures flexibility, whereas our managed service, Zilliz Cloud, delivers enterprise-grade efficiency with minimal operational complexity.
Are you able to elaborate on the importance of Zilliz Cloud and its function in democratizing AI and making vector search companies accessible to small builders and enterprises alike?
Vector search has been utilized by tech giants since 2015, however proprietary implementations restricted its broader adoption. At Zilliz, we’re democratizing this know-how by way of two complementary approaches:
- Open Supply: Milvus permits builders to construct and personal their vector search infrastructure, reducing technical boundaries.
- Managed Service: Zilliz Cloud eliminates operational overhead, providing a easy, cost-effective resolution for companies to undertake vector search with out requiring specialised engineers.
This twin strategy makes vector search accessible to each builders and enterprises, enabling them to concentrate on constructing progressive AI purposes.
With developments in LLMs and basis fashions, what do you imagine would be the subsequent huge shift in AI knowledge infrastructure?
The following huge shift would be the wholesale transformation of AI knowledge infrastructure to deal with unstructured knowledge, which makes up 90% of the world’s knowledge. Present techniques, designed for structured knowledge, are ill-equipped for this shift.
This transformation will affect each layer of the information stack, from foundational databases to safety protocols and observability techniques. It’s not about incremental upgrades—it’s about creating new paradigms tailor-made to the complexities of unstructured knowledge.
This transformation will contact each side of the information stack:
- Foundational database techniques
- Knowledge pipelines and ETL processes
- Knowledge cleansing and transformation mechanisms
- Safety and encryption protocols
- Compliance and governance frameworks
- Knowledge observability techniques
We’re not simply speaking about upgrading present techniques – we’re constructing fully new paradigms. It is like transferring from a world optimized for organizing books in a library to at least one that should handle, perceive, and course of your entire web. This shift represents a complete new world, the place each part of information infrastructure may must be reimagined from the bottom up.
This revolution will redefine how we retailer, handle, and course of knowledge, unlocking huge alternatives for AI innovation.
How has the mixing of NVIDIA GPUs influenced the efficiency and scalability of your vector search?
The mixing of NVIDIA GPUs has considerably enhanced our vector search efficiency in two key areas.
First, in index constructing, which is without doubt one of the most compute-intensive operations in vector databases. In comparison with conventional database indexing, vector index building requires a number of orders of magnitude extra computational energy. By leveraging GPU acceleration, we have dramatically lowered index-building time, enabling sooner knowledge ingestion and improved knowledge visibility.
Second, GPUs have been essential for high-throughput question use instances. In purposes like e-commerce, the place techniques have to deal with 1000’s and even tens of 1000’s of queries per second (QPS), GPU’s parallel processing capabilities have confirmed invaluable. By using GPU acceleration, we are able to effectively course of these high-volume vector similarity searches whereas sustaining low latency.
Since 2021, we have been collaborating with NVIDIA to optimize our algorithms for GPU structure, whereas additionally growing our system to assist heterogeneous computing throughout totally different processor architectures. This provides our prospects the pliability to decide on probably the most appropriate {hardware} infrastructure for his or her particular wants.
As vector databases play a vital function in AI, do you see their utility extending past conventional use instances like suggestion techniques and search to industries like healthcare?
Vector databases are quickly increasing past conventional purposes like suggestion techniques and search, penetrating industries we by no means imagined earlier than. Let me share some examples.
In healthcare and pharmaceutical analysis, vector databases are revolutionizing drug discovery. Molecules will be vectorized based mostly on their practical properties, and utilizing superior options like vary search, researchers can uncover all potential drug candidates that may deal with particular illnesses or signs. Not like conventional top-k searches, vary search identifies all molecules inside a sure distance of the goal, offering a complete view of potential candidates.
In autonomous driving, vector databases are enhancing car security and efficiency. One attention-grabbing utility is in dealing with edge instances – when uncommon situations are encountered, the system can rapidly search by way of large databases of comparable conditions to search out related coaching knowledge for fine-tuning the autonomous driving fashions.
We’re additionally seeing progressive purposes in monetary companies for fraud detection, cybersecurity for menace detection, and focused promoting for improved buyer engagement. As an example, in banking, transactions will be vectorized and in contrast in opposition to historic patterns to determine potential fraudulent actions.
The ability of vector databases lies of their capacity to know and course of similarity in any area – whether or not it is molecular buildings, driving situations, monetary patterns, or safety threats. As AI continues to evolve, we’re simply scratching the floor of what is potential. The flexibility to effectively course of and discover patterns in huge quantities of unstructured knowledge opens up prospects we’re solely starting to discover.
How can builders and enterprises greatest interact with Zilliz and Milvus to leverage vector database know-how of their AI initiatives?
There are two important paths to leverage vector database know-how with Zilliz and Milvus, every fitted to totally different wants and priorities. In case you worth flexibility and customization, Milvus, our open-source resolution, is your most suitable option. With Milvus, you possibly can:
- Experiment freely and study the know-how at your personal tempo
- Customise the answer to your particular necessities
- Contribute to improvement and modify the codebase
- Preserve full management over your infrastructure
Nonetheless, if you wish to concentrate on constructing your utility with out managing infrastructure, Zilliz Cloud is the optimum alternative. It affords:
- An out-of-the-box resolution with one-click deployment
- Enterprise-grade safety and compliance
- Excessive availability and stability
- Optimized efficiency with out operational overhead
Consider it this manner: in case you get pleasure from ‘tinkering’ and need most flexibility, go along with Milvus. If you wish to decrease operational complexity and get straight to constructing your utility, select Zilliz Cloud.
Each paths will get you to your vacation spot – it is only a matter of how a lot of the journey you need to management versus how rapidly you’ll want to arrive
Thanks for the good interview, readers who want to study extra ought to go to Zilliz or Milvus.